
Context
This project brought large language models into a production workflow for clinical notes at the VA Office of Connected Care, focused on continuous glucose monitoring (CGM) data. It had to run inside VA data governance and multi-cloud GovCloud constraints.
I authored the abstract and presented to VA stakeholders twice to secure approval. The result became the first LLM pipeline to reach production at the VA.
What I built
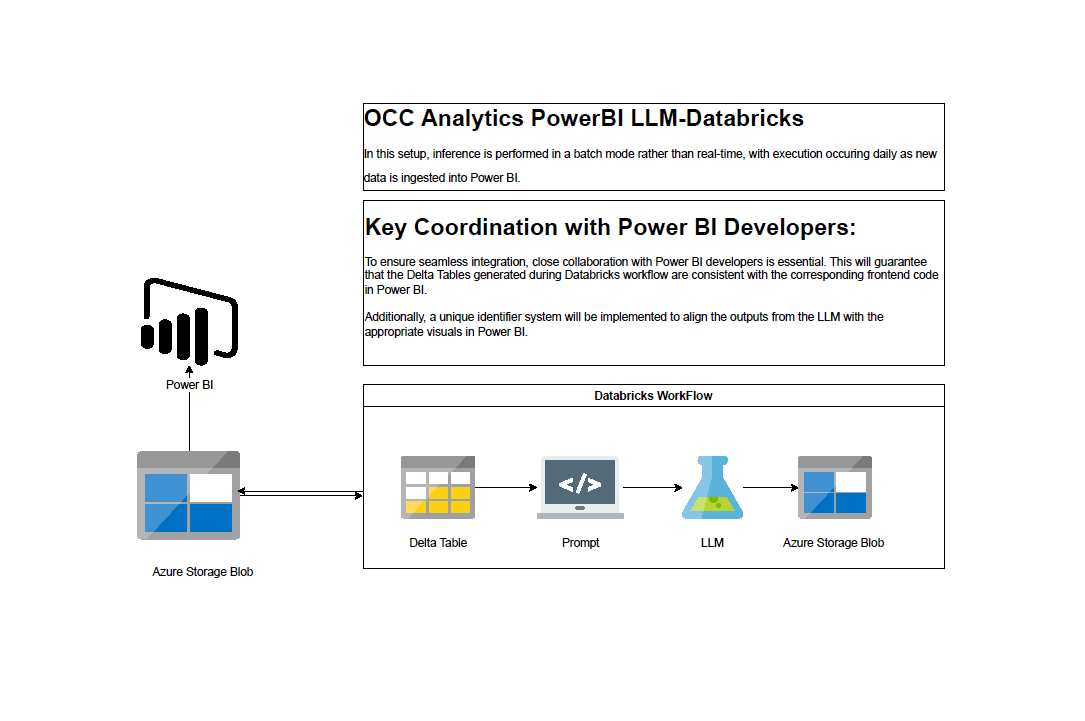
- An end-to-end Azure Databricks workflow that ingests relevant laboratory data, particularly glucose values, from Parquet files into Delta tables.
- Prompt construction, LLM inference on a GPU-enabled cluster, and automated verification of results.
- Daily batch inference that runs as new data arrives, writing outputs to Azure Blob Storage for Power BI.
- Designed a unique-identifier scheme to align each LLM output with the matching Power BI visual, coordinating closely with the Power BI developers.
- MLflow experiment tracking and registry, following the conventions I set for the data science team.
Results
- Became the VA's first production LLM pipeline.
- Still running in automation, with an estimated $5M+ in annual savings.
- Approved after two stakeholder presentations, with the abstract I authored.